We train models and turn them into useful technology.
EarlySearch, EarlyOffice, EarlyDesign, EarlyBot, EarlyZip, EarlyRemote. From the engines behind our products to research for the next model, explore the technical problems we tackle ourselves.
Models for our own problems, developed by us.
A step beyond using existing models. We prepare training data and fine-tune models, connecting runtime environments and evaluation.
Data designImages, captions and document tasks
TrainingPurpose-specific fine-tuning and adapters
Model artifactsSave and reopen, convert and check compatibility
InferenceLocal execution and memory placement
EvaluationOutput quality and real product tasks
We currently work on fine-tuning existing models and developing runtimes. Training runs, model quality evaluation and product integration are verified separately.
In productDevelopment · researchChoose a topic to read about its implementation and next challenges.
AI search that breaks down questions and connects evidence.
EarlySearchIn product · being refined
We go beyond summarising search results, building technology that investigates a question from several directions and rechecks the answer's citations and figures.
1Break down the question
2Search the web and read pages
3Generate an answer
4Check citations and numbers
Search, generation and verification are separate stages.
Quick answers find relevant material and summarise it briefly; deep research creates subquestions and investigates several directions. After an answer is written, code checks citation-number ranges, whether paragraphs contain citations, and whether figures appear in the collected evidence.
A closer technical look +
Checks record the locations of problematic paragraphs, lists and tables. This lets us review the relevant passages rather than rewrite the entire answer.
Matching figures and linked sources do not guarantee correct meaning. We research ways to check reliability, units, timing and context together.
Next challenges
We are improving how to judge conflicting sources, distinguish old and new material, and trace evidence throughout long research tasks.
Document structure and layout beyond file formats.
EarlyOfficeIn product · improving precision
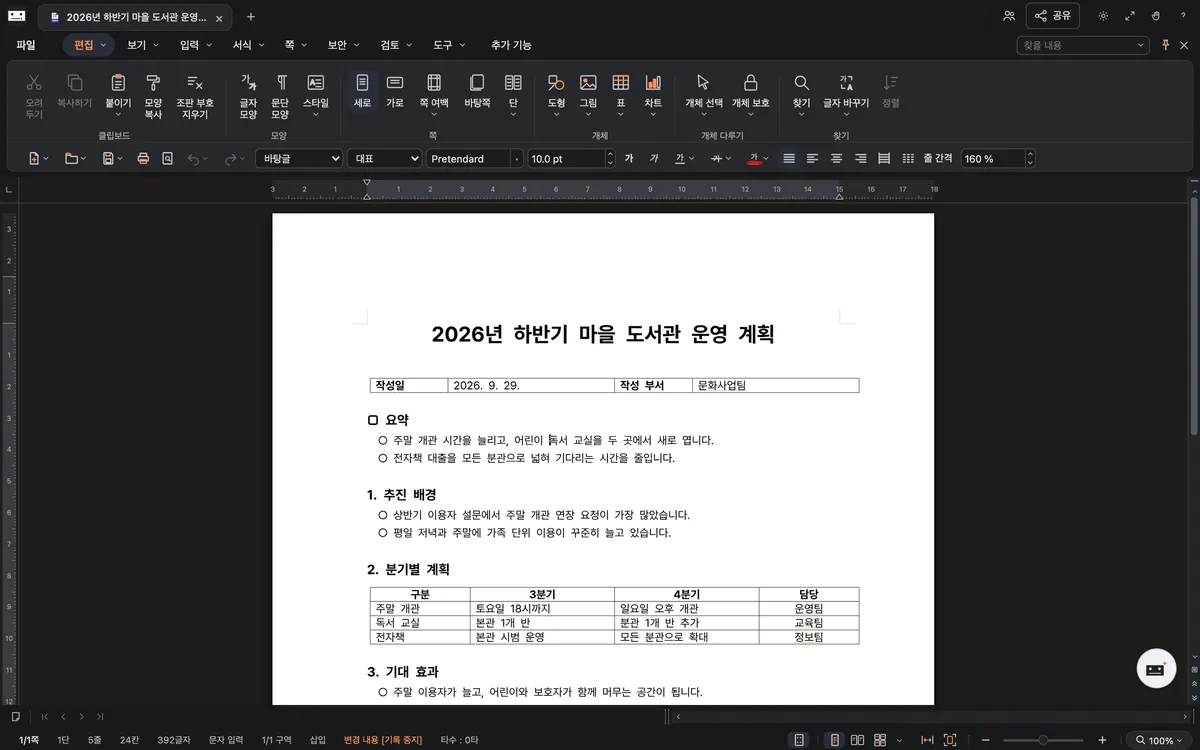
Within a product for Hangul and Word documents, spreadsheets, presentations and PDFs, we research format interpretation, editing models, fonts and layout calculation.
An actual EarlyOffice screen using the document engine
1Interpret the file
2Shared document model
3Edit and calculate layout
4Screen and PDF output
Technology to read a document, and to draw it as a document.
Text extraction alone cannot preserve tables, page breaks, equations and image positions. We manage document structure and editing state, using real font-file information to calculate layout. A shared Rust core on web and desktop helps reduce platform differences.
A closer technical look +
Layout uses integer document units and consistent rounding rules. Calculated drawing data feeds screen and PDF output, which we compare with original document output to track differences.
Separate engines for spreadsheet calculation, slide objects and PDF processing connect to the same product experience. Features and fidelity differ by format; this does not mean perfect compatibility with every file.
Next challenges
Ongoing challenges include complex table pagination, font substitution, object positioning and reducing conversion loss between formats.
From AI that writes text to AI that edits documents.
EarlyOfficePrototype · under research
We research tool-based document AI that understands paragraphs and tables, edits selected parts and checks layout.
1Read document structure
2Propose edits through tools
3Check layout
4Accept or undo
Record what changed, where and how.
Instead of handing the whole document to AI as text, we provide tools to read and edit semantic units. We identify edit locations and check whether old requests conflict with the user's latest changes. We are building a reviewable proposal flow.
A closer technical look +
Stable paragraph and table identifiers work with document revision data. We check layout after edits and experiment with undoing one request's changes as a single group.
This is development and prototype work connecting the editing core and AI tools. The complete flow described here is not generally available in every product screen.
Next challenges
We research selecting context in long documents, reviewing edits to tables and layout, and preserving user intent.
One graphics editing engine for web and apps.
EarlyDesignIn product · expanding compatibility
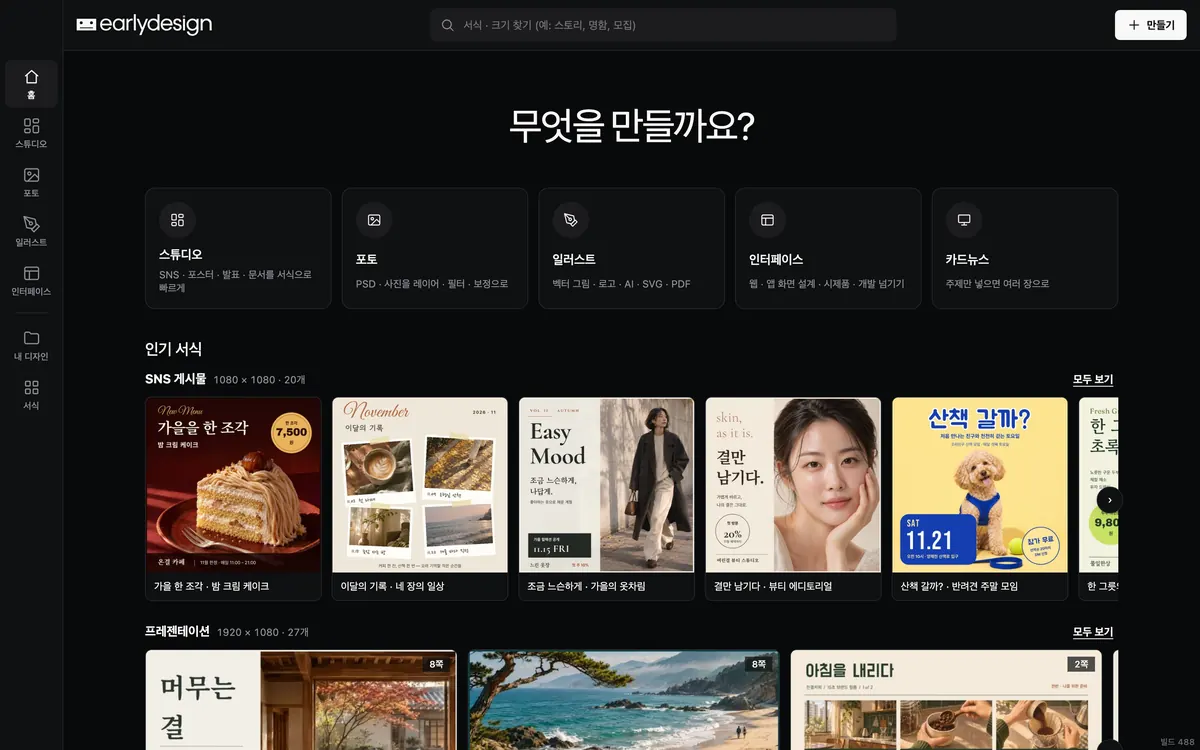
Rather than building separate editors for templates, photos, vector illustration and screens, we build a layer-and-object editing engine shared by browsers and native apps.
The actual EarlyDesign home screen using the graphics engine
1Read the original file
2Layer and object model
3Render through the engine
4Save in the original format
Different screens, the same editing engine.
A Rust engine manages document state and editing commands for Studio, Photo, Illustration and Interface. Browsers use WebAssembly; iPhone, iPad and Android apps connect natively to the same core to draw the same document the same way. Several engine steps for one user action form one undo operation.
A closer technical look +
The erase tool fills photo regions using an openly licensed inpainting model inside the browser. Photos stay on the device; if the model is unavailable, it falls back to the engine's fill method.
Our image-to-vector tracing groups colours in a perceptual colour space and handles corners and small fragments. Evaluation tools measure colour differences between originals and redraws to compare and refine each preset.
Editing commands are exposed as a defined set of names and arguments. The AI helper uses the same commands through MCP and browser WebMCP; connections are off by default, and document-changing commands require user confirmation.
Next challenges
We are extending fidelity for layer effects and vector features, while balancing memory for large documents with on-device model quality and speed.
We research paired image-caption data, image-model fine-tuning and flows that turn natural-language requests into image generation.
1Prepare images and captions
2Fine-tune
3Conditional image generation
4Compare results
Good results start with data and the generation process.
We work on preprocessing that captions images and prepares training data, experimenting with fine-tuning existing image models for specific purposes. Separately, we are building a prototype that converts Korean conversations into generation requests and connects them to image generation.
A closer technical look +
Research builds on a caption pipeline for image-text pairs, LoRA fine-tuning artifacts, and code that constructs prompts from conversations and sends them to a generation engine. We distinguish using and fine-tuning existing models from developing a foundation model.
Running training and concluding that model quality improved are separate matters. We do not claim established performance or generality for models in training; we compare generated results and data effects under the same conditions.
Next challenges
We examine image-caption alignment, preservation of intended visual features, data bias and rights, and consistent expression of requested scenes.
An agent that keeps working after the conversation ends.
EarlyBotDevelopment build · expanding execution
We develop long-running task structures that turn requests into tasks, save execution state, obtain approvals and verify results.
1Goal and plan
2Approval and tool execution
3Save state and resume
4Verify and notify
An answer is distinct from an action.
EarlyBot manages task runners and scheduled state separately from chat. While its server is running, it processes schedules even after a web tab closes, recording states such as waiting for connection, running, review and completion. The key is separating model-proposed actions from permission to run real tools.
A closer technical look +
Tasks, schedules, run history, results and notifications are stored persistently, with duplicate runs limited. App, browser and device execution paths are configured to check the approvals and results belonging to each task.
We distinguish verified development environments from supported-tool scope. We do not claim autonomous completion of every external task or execution while the PC is powered off.
Next challenges
We are refining resumption after interruption, verification across several tools, failure recovery and when users should intervene.
Toward context you do not have to explain again.
EarlyBotImplemented in development · expanding evaluation
We organise preferences, decisions and past work as memories with sources and timestamps, retrieving the context needed for new requests.
1Record the original
2Organise sources and timing
3Retrieve relevant memories
4Apply edits and exclusions
Memory needs sources and change history as well as content.
We combine an original-text search index with structured memories. Statement timing prevents older conversations processed later from overwriting recent corrections, and we avoid retrieving content users have corrected or excluded.
A closer technical look +
We find relevant records for new conversations and plans while distinguishing saved originals from AI interpretations. Even retrieved candidates have their owner and active state checked again in storage.
Memory grants no new execution authority. Remembering a past statement does not replace approval for a new task. We do not describe current development as completed commercial multi-user isolation.
Next challenges
We research precedence between older memories and recent decisions, retrieval relevance, correction of mistaken memories and long-term accuracy evaluation.
From older archive formats to safe file handling.
EarlyZipIn development builds · expanding verification
We develop format interpretation for ALZ, EGG and Korean filenames, platform-specific archive processing and storage methods that protect files when a task fails.
1Interpret formats and names
2Check paths and conflicts
3Extract and check integrity
4Commit completed results
Opening a file is only the start of handling it correctly.
Older Korean encodings and archive formats require more than recognising extensions. We connect a shared engine with platform implementations, checking out-of-folder paths, name conflicts and incomplete output. User archives are processed on the device.
A closer technical look +
Fuzzing and regression tests repeatedly input valid, damaged and truncated files to detect crashes, hangs, excessive resources and writes outside the intended path. We distinguish supported formats from verified variants.
Buffer reuse, synchronisation and parallel work for many small files are also improvement areas. Measurements from different platforms and workloads are not generalised into a single speed claim.
Next challenges
We continue checking rare variants, platform scope for encrypted and split archives, mobile storage and background-processing constraints.
Running large models with limited resources.
Model and document AI researchVerified in development · performance research
We research how to place model data and memory for local document AI, treating execution resources separately from model quality.
1Inspect model structure
2Allocate memory budgets
3Use SSD, RAM and GPU
4Compare under equal conditions
Inference speed and memory must be considered together.
We experiment with runtimes that distribute model data across SSD, RAM and GPU memory and connect it to the necessary computation. Keeping the full model structure, we compare static placement with dynamic expert caching, observing time to first answer and I/O costs together.
A closer technical look +
Development checks connecting document creation, editing, saving and reopening to the real editor are separate from fine-tuning and model-runtime performance checks. Running on particular hardware does not establish minimum requirements for all users.
Dynamic caches are not always faster. We compare against baseline runs with matched outputs, loads and conditions, and record experiments even when no improvement is confirmed.
Next challenges
We separately evaluate placement-related latency and disk access, cache replacement policies, hardware stability and model quality.
Connecting screens and separating execution authority.
We research remote video and input, separation of viewing and control, and approvals and state management when AI tasks use real devices.
1Capture and encode screens
2Transmit video and input
3Check control authority
4Handle connection loss
Being connected is different from being allowed to control.
Screens travel as video while keyboard and mouse input use a separate path. We separate viewing sessions from control authority and handle device state, such as releasing held keys and buttons after a disconnect. Agent file and app tasks are being connected to the scope users permit.
A closer technical look +
We verified actual remote video and input paths between trusted development devices. File handling ties approved plans to result verification. Local connection checks are not evidence for general internet connectivity or gaming performance.
Screen-capture and input permissions, host OS constraints, interruption and recovery are separate problems. We build flows that let us observe model plans separately from real device execution.
Next challenges
We are expanding checks for latency and quality across connections, long-session stability, OS permission and input differences, and remote-task verification.
Technology is measured by the people using it.
Connect data all the way to products.
We treat training data, model execution, engines and user experience as one problem.
Verify with real tasks.
We inspect real artifacts: reopened generated documents, extracted-file integrity, differences between rendered images and originals, and the results of executed tasks.
Record development and evaluation together.
We distinguish running training from improving quality, and development checks from product integration.
Build the next technology together.
Model development, document, graphics and file engines, AI agents. We welcome partners who connect technology and products.